Alert on symptoms
Pages fire on what the customer feels, not on what a dashboard happens to measure.
Staff Site Reliability Engineer
SRE who treats an outage as a design review that arrived late.
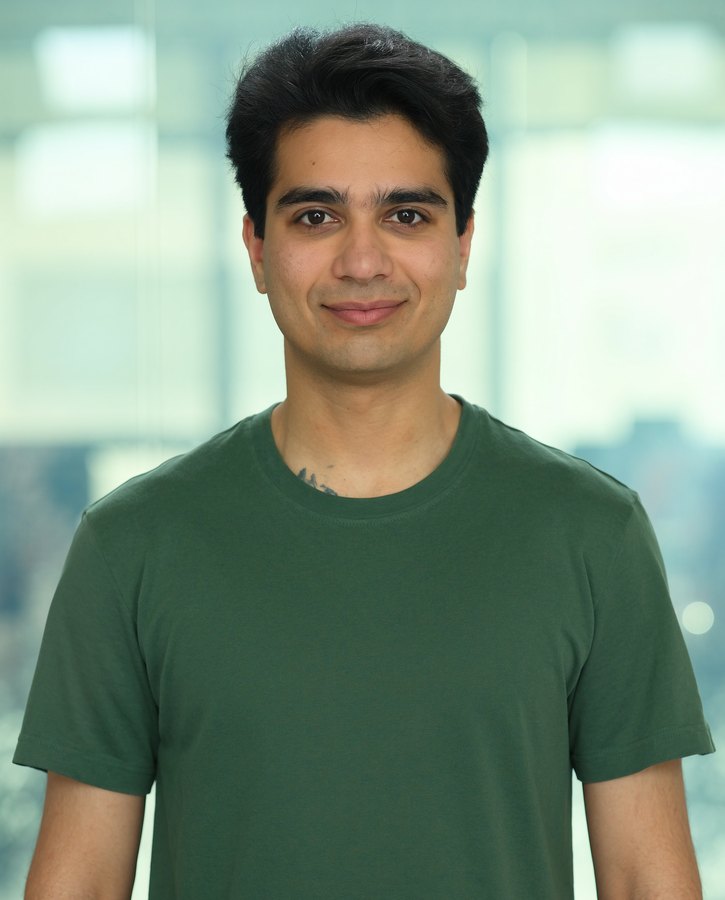
Six years keeping payment infrastructure up, and a habit of writing the postmortem nobody dreads reading. Happiest on a team that wants fewer pages, not more dashboards.
# average pages per on-call week, payments tier
Pages fire on what the customer feels, not on what a dashboard happens to measure.
The postmortem names the system that failed and the change that stops it, never the person on call.
Does it by hand once, writes the runbook, then deletes the runbook by automating it.
2023 to nowStaff SRE(current, Kelsey Pay)
2020 to 2023Senior SRE(Latchbox)
2018 to 2020Backend engineer(Vero Logistics)
A page has to be urgent, actionable and real, or it gets deleted. Every alert has an owner and a runbook, and the runbooks are reviewed every quarter.
Hand-offs are written, not verbal. Whoever comes on reads one page and knows what is burning and what is only smoking.
Kiran rewrote our alerting and the on-call rotation stopped burning people out. Retention on that team went up.
His postmortems are the only ones I read end to end. They say what broke and what changes, and nothing else.
Postmortem samples and references on request.